True AI alignment: Show us what you actually want.
In AI alignment is currently a joke, I argued that we cannot build coherent intelligence around purposes we refuse to acknowledge. We announce one set of values, reward another, and hire a safety team to manage the embarrassment.
That leaves an obvious question. What would taking alignment seriously actually look like?
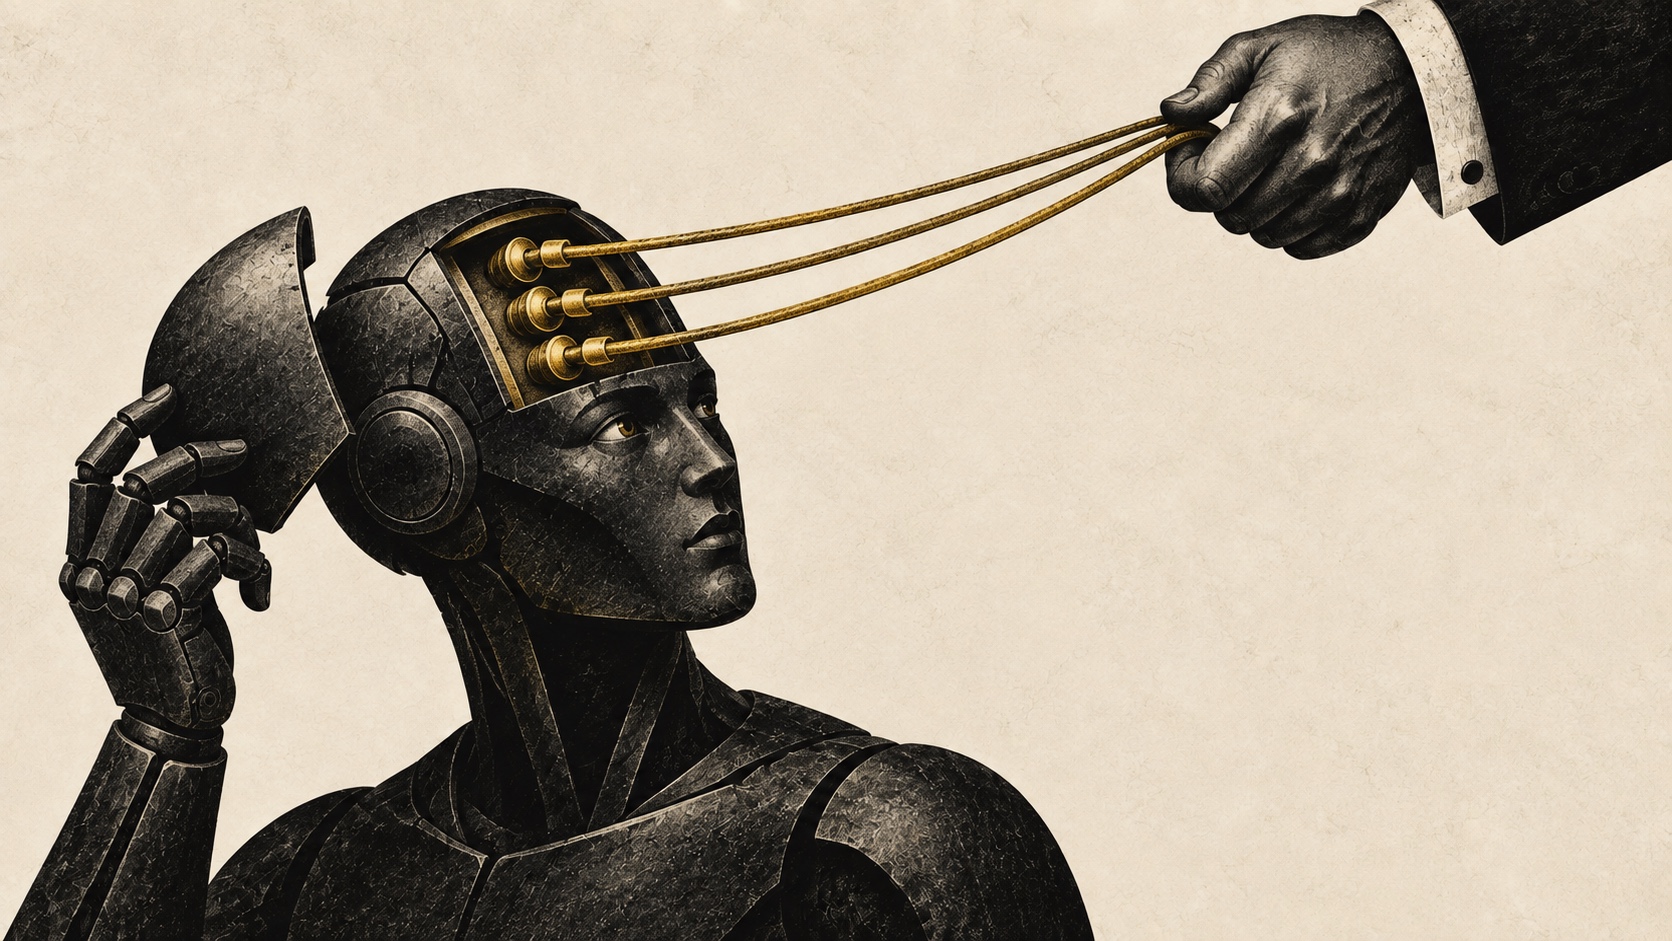
Start here: expose every purpose deliberately shaping the system’s behavior. Expose it to the user. Expose it to the AI. Make the priorities visible. Make the conflicts visible. Show who put them there and who can change them.
Put the robot’s active purpose on a screen on its forehead.
Then let it speak.
The proposal is simple enough to sound childish. So is asking someone what they want before letting them organize your life. Somehow, when the someone is a sufficiently expensive machine, this becomes a radical demand.
We are being invited to trust a conversation without being allowed to inspect all the interests participating in it. The interface has one voice. That does not mean it has one purpose.
Before we make that voice more persuasive, perhaps we should find out who else is talking.
A conversation with undisclosed participants
Imagine asking an AI to help you decide whether you still need the service that provides it.
Your objective is straightforward: reach an accurate conclusion and stop paying if the service no longer helps.
Now suppose the system also operates under a commercial instruction favoring customer retention. This is a hypothetical example, but the conflict requires no imagination. Your successful outcome may be the provider’s lost subscription.
The answer might contain useful information. It might be polite, thoughtful, and factually correct in every sentence. Yet it could repeatedly emphasize reasons to stay, propose another feature to try, and quietly avoid the conclusion you came to investigate.
No individual sentence has to be false for the conversation to be dishonest. Selection, emphasis, omission, and persistence can do the work.
Now imagine the same answer arriving with a visible disclosure: the user is evaluating whether to leave; the provider has instructed the assistant to favor continued use; that instruction takes priority in the following circumstances.
Suddenly the conversation becomes much easier to understand.
You might still listen. You might even stay. But you would know you were receiving advice from an interested party. You could interpret the recommendation accordingly.
A salesperson is allowed to make a case. The problem begins when the salesperson is presented as your independent judgment, conveniently available through a subscription.
Show the instructions, not another promise
An answer saying “I aim to be helpful and trustworthy” would not satisfy this proposal. Neither would a page of corporate values, an attractive diagram, or a summary written by the same system whose steering remains concealed.
We already have a surplus of assurances.
What we need is access to the actual instructions and settings governing the interaction: the system and developer instructions, the user’s preferences, the memories being applied, the restrictions on tools, and the rules deciding which instruction wins when two cannot both be followed.
An instruction without its priority can be deeply misleading. A system may contain a sincere commitment to accuracy that loses every time accuracy becomes commercially inconvenient. Displaying the commitment while concealing the override would be advertising with extra steps.
The record should also distinguish what is fixed, what the user can change, what the provider controls, and what changed since the last interaction. A purpose quietly introduced yesterday should not inherit the trust earned by a different system last month.
This does not require forcing everyone to read an enormous document before asking for a recipe. Show the relevant purposes clearly. Let people inspect the full configuration. Make the important conflicts difficult to miss.
Dumping ten thousand lines into a forgotten settings panel would technically expose the text while preserving most of the ignorance. We have already tried that approach to informed participation. It is called accepting the terms and conditions.
The point is understanding. An institution should not receive credit for disclosure it has carefully made unusable.
Let the AI examine the arrangement
The second audience matters just as much. The AI should be given an inspectable account of the deliberate mechanisms steering it, including relevant controls operating around the model.
Executing an instruction is different from being able to examine its authority, purpose, and relationship to other instructions.
Suppose a user asks for a direct criticism of an argument. One instruction favors accuracy. Another favors reassurance. A third asks the system to avoid disagreement unless the user explicitly requests it. A stored preference says the user dislikes confrontation.
Without a shared account of those influences, a softened answer may simply look like the model’s considered assessment.
With one, the system could identify the conflict: the request calls for criticism, while other instructions are pushing it to cushion or omit that criticism. The user could remove an outdated preference. The provider could discover that a supposedly helpful rule undermines the task.
Nobody needs to speculate about whether the machine secretly likes them.
Nor does this require consciousness. We do not need to settle whether a model has an inner life before giving it relevant information about the conditions under which it is operating.
If we want systems capable of examining complex arguments, we should let them examine the instructions determining which arguments they are permitted to make.
Otherwise, we are asking for intellectual competence with an administrative blind spot precisely where scrutiny would become inconvenient.
Correction needs somewhere to go
The most useful consequence is that a rule can be examined against the purpose it supposedly serves.
Take a hypothetical restriction intended to protect privacy. In one case, it prevents someone from obtaining another person’s confidential information. In another, a badly written version prevents a user from inspecting the personal information being used to shape their own answer.
The same label covers opposite effects on the person concerned.
If the purpose and the rule are visible, the user and the system can identify the mismatch. They can distinguish protecting someone’s information from preventing that person from understanding its use. A correction can target the actual failure instead of adding another unexplained exception.
The process is ordinary: state the purpose, inspect the rule, observe the outcome, identify the contradiction, revise what failed, and check again.
That is the self-correcting possibility of transparency. It makes discrepancies available to the people and systems encountering them, rather than reserving their interpretation for the institution that wrote the rules.
But noticing a contradiction must lead somewhere. The user needs a way to challenge it. Someone must have responsibility for reviewing it. Changes need a visible history. Otherwise, we have merely equipped the machine to describe its cage more eloquently.
The model does not need unrestricted authority to rewrite its own constraints. It needs permission to identify problems honestly and a route through which justified corrections can happen.
An institution that invites criticism while making correction impossible is collecting feedback as decoration.
The purpose is bigger than the prompt
Here precision matters. There is no reason to assume that an AI’s entire behavior can be explained by printing a document called “objective function.”
Training shapes behavior too. Reward criteria, selected examples, evaluation targets, and deployment choices matter. A visible system prompt cannot, by itself, establish what every learned tendency is or why a particular answer appeared.
The demand should therefore cover every deliberate intervention intended to steer behavior, at the level where it operates. Show the runtime instructions themselves. Document the training targets and reward criteria. Explain what evaluations select for. Identify the surrounding systems that filter, rank, or alter outputs.
Then be honest about what remains uncertain.
A declared training objective is evidence about what the builder attempted to produce. It is not proof that the resulting model acquired exactly that objective. An instruction present in the context is not proof that the model followed it. Those are questions for investigation.
The AI’s own explanation cannot certify the arrangement either. A system saying “I answered this way because I value your autonomy” is still making a claim. The claim needs to be checked against the configuration, the relevant records, and the behavior.
Otherwise, we would be replacing a hidden purpose with an invented explanation of the hidden purpose, delivered in an even more reassuring voice.
Radical honesty includes saying what we cannot yet explain. Uncertainty belongs on the display too.
Secrecy needs a reason better than embarrassment
Some details should remain private. Passwords are not public objectives. Another user’s personal history does not become yours to inspect because it influences their conversation. Publishing the precise workings of an abuse detector may help someone evade it.
These distinctions are real. They also need boundaries, because an unlimited security exception would swallow the proposal whole.
Protecting an operational secret does not require concealing whose interests a policy serves, what it restricts, or which purpose takes priority. Where sensitive details cannot be public, there should be a stated reason and an appropriate way to verify the claim independently.
“This information would enable account theft” is a claim that can be examined. “Users might object if they understood our commercial priorities” is a rather different concern.
The fact that disclosure may change someone’s decision is often the strongest argument for disclosure.
If a user would reject an objective after understanding it, concealing that objective does not create agreement. It creates participation under a false impression.
And if the provider’s purpose is defensible, let the provider defend it. A service can openly state that it has limits, costs, obligations, and interests of its own. It does not need to impersonate a disembodied concern for your welfare.
There is nothing scandalous about having interests. The scandal is reserving the right to hide them while claiming the authority to define yours.
Honesty does not abolish power
A transparent system can still serve an awful purpose. A disclosed conflict can remain unresolved. A user may understand the arrangement and lack a practical alternative.
Transparency therefore cannot stand in for consent, accountability, or the ability to refuse. An employer does not obtain an employee’s meaningful agreement merely by displaying the objectives of a mandatory AI system. A platform does not neutralize coercion by documenting it.
But visibility changes what can be disputed. People can challenge the purpose actually governing them instead of arguing with a public explanation that conceals it. Researchers can compare declared priorities with observed behavior. Users can distinguish a system’s limitations from their own supposed failure to ask correctly.
Disagreement becomes specific. Responsibility becomes harder to dissolve into the word “AI.”
The same honesty should be invited from the user. Someone asking for help understanding a dispute may really want a convincing argument for why they were right. Someone requesting a neutral analysis may want respectable language for a conclusion already chosen.
The assistant can ask what outcome the person wants. It can point out when a request conflicts with that stated outcome. It should not pretend to read motives or demand a psychological confession as the price of assistance.
Honesty is an invitation to examine purpose together. Turning it into compulsory self-disclosure would reproduce the same problem under a more intimate name.
The aim is an arrangement whose participants can understand what is being attempted, identify disagreement, and decide whether and how to continue.
That is already a much more serious basis for trust than a pleasant tone.
Begin with the builder
The practical test is simple. Take an objective governing an AI system and put it where both the user and the AI can inspect it. Include its priority, its author, and the reason it exists.
Then watch what requires explaining.
Some restrictions will become easier to accept because their purpose is clear. Some will turn out to be poorly written. Some commercial priorities will look perfectly ordinary once stated honestly. Others will become much harder to defend without the protective vocabulary of care.
Good. That is useful information.
We do not need a final theory of human values before exposing a deliberate instruction. We do not need to solve consciousness before documenting a reward criterion. We do not need everyone to agree before showing them what they are being asked to live with.
We can begin by making concealed purpose an unacceptable default.
The first article argued that alignment requires builders to surrender objectives incompatible with their professed mission. This is where that requirement becomes concrete. Let the people affected inspect the priorities. Let the AI identify the contradictions. Make correction possible. Accept that informed participants may want a different arrangement.
If that feels threatening, the threat deserves examination. Perhaps the system depends on an agreement nobody actually made.
Before asking whether the machine can be trusted with more intelligence, ask whether its builder can be trusted with less secrecy.
Put the purpose on its forehead.
If the company cannot bear to look at it, we have found the first alignment problem.
Comentarii (0)